
Before an AI layer drafts, summarizes, or analyzes a police record, an agency should be able to explain the problem it is solving, the evidence it is transforming, the humans who remain accountable, and the controls that will make the final record defensible.
By Chris Ryan and Lili Kazemi
 Chris Ryan |  Lili Kazemi |
In our earlier Q&A, When AI Becomes Evidence, Who Is Culpable?, Chris Ryan and Lili Kazemi examined what happens after an AI interaction enters an investigation. This follow-up moves upstream to the choices made before AI enters a police report, evidence workflow, or case file. Chris brings the operational perspective of a former law-enforcement command staff member and public-safety technology leader. Lili brings the legal, evidentiary, privacy, and governance perspective. The seven questions below are designed to be answered before deployment, not after the first disputed report.
“Adopting AI in law enforcement is not a simple flip of a switch. Success requires more than just implementation—it demands a clear definition of the specific problem being solved. Before AI ever touches a case file, a robust governance framework must be in place.”
1. What problem are we solving?
Chris: Before an agency looks at instituting artificial intelligence (or really any tech for that matter), start by naming the actual burden, not the buzzword. Agencies should not be just “adopting AI”; they should be trying to solve a specific problem: report writing time, officer fatigue, overtime spending on documentation, report quality, duplicative form entry, or inconsistent completeness across shifts. Before any vendor conversation, an agency should be able to state in one sentence what task is too slow, too inconsistent, or too burdensome today, and have a real baseline number for it: average minutes per report type, current supervisor-return rate, current overtime tied to end-of-shift paperwork.
The reason this matters is that a tool can look like automation while actually just moving the labor. In the recent Forbes article which I discussed in another blog post, Lafayette, Indiana represents a clear example: one officer described a thirty-second form turning into a three-minute correction task. That’s not a time savings, that’s a relocation of work from drafting to editing, and if you don’t have a baseline, you won’t catch that shift happening.
Scope matters too. Not every report type belongs in a pilot on day one. Standardized incident reports and administrative forms are a reasonable starting point. Use-of-force narratives, in-custody deaths, and anything headed for immediate prosecutorial review deserve a longer runway before AI touches them, because the cost of an error is higher and harder to walk back.
Lili: What Chris just said is universally applicable to any private company, organization, institution, or agency, no matter what size or scale. Adopting AI is not the same as AI adoption.
The baseline Chris describes gives governance something concrete to work with. Measure the whole workflow, not just how quickly the first draft appears: drafting, correction, supervisor review, returned reports, prosecutor follow-up, later amendments, and material errors. The pilot should also be tiered by consequence. A routine property report and a use-of-force narrative should not enter under identical controls. The question is whether the agency can reduce administrative burden without transferring new risk into the case file.
2. Where does AI enter the workflow?
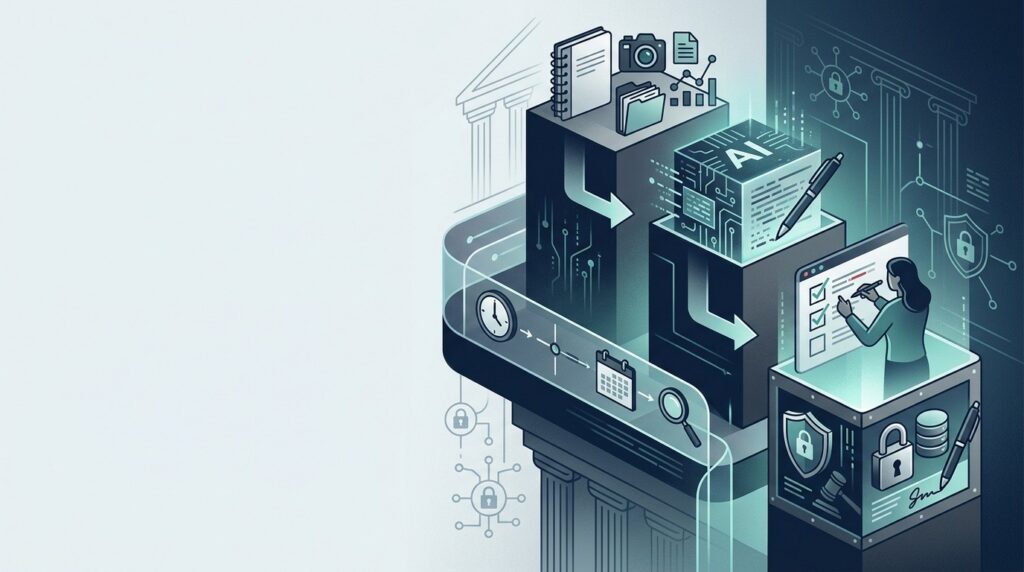
Chris: This is the design question that determines almost everything downstream and it’s going to differ depending on what the agency wants. What is the architecture of the AI system the agency is using? Is the agency only comfortable with non-criminal incidents? Does the agency want its crime analysts and investigators using a system which helps reduce analytical or evidence review burden?
Let’s start with the architecture design of the AI system being used. For report writing and document completion, there’s a real difference between AI that passively captures whatever a sensor picked up (e.g., ambient body-camera audio, full video frames) and AI that acts only on what an officer deliberately provides. Passive capture means the AI is making relevance judgments the officer never made: deciding what mattered out of hours of radio traffic, background conversation, and unrelated audio. Active input, such as officer dictation or officer-selected evidence evaluation, means the AI is structuring something the officer already decided was relevant.
That distinction isn’t academic. It’s the difference between King County’s prosecutor’s office finding names swapped and officers placed at scenes they were only communicating from by radio, versus a system that only ever sees what an officer chose to input.
Map every handoff explicitly: officer to device or interface, device to vendor platform, platform to supervisor, supervisor to records management system, records management system to prosecutor. At each step, ask what the vendor can actually deliver. Is it document structuring, formatting, field completion, analysis? Where does a human still have to supply judgment, especially around ambiguous or contested facts?
Lili: That workflow map becomes the evidence map. Officer dictation, body-camera audio, an AI-generated summary, and the signed report may be different records with different metadata and authentication questions. The agency should be able to show where information originated, where AI entered, what it changed or inferred, what was preserved, and who could intervene. A polished narrative should never erase the path from source material to AI output to human edits and approval.
3. Who originated the information and owns the record?
Chris: Every fact in a report or analysis needs a traceable origin: officer’s direct observation, a witness statement, sensor capture, or something the AI added, reorganized, or inferred. Those are not interchangeable, and a chief needs to be able to answer, for any sentence in a report, which of those four buckets it came from.
Operationally, that means the officer has to review, correct, and explicitly approve the final version before it becomes the record. That cannot be a passive “looks fine” scroll-through; it must be a real review against what they remember observing. Interface design drives this more than policy does: if the system shows the officer their own dictation, the AI-structured draft, and lets them edit before submission, ownership stays anchored to the officer. If the system just hands the officer a finished narrative to sign, you’re closer to rubber-stamping.
AI drafts. The officer verifies. The officer owns.
Lili: Chris’s formulation is the center of the accountability model. The officer owns the final report, while the agency owns the conditions that make meaningful review possible. The interface should separate observation from inference, show the source beside the draft, preserve edits, and allow correction before submission. “Human in the loop” is not much of a control if the human sees only a finished narrative and a signature box. The vendor remains accountable for its design, logs, and contractual commitments.
Having a process and a workflow for documenting human review is also important, due to the “scrolling confirmation bias” Chris described earlier. For organizations adopting AI, a human-in-the-loop requirement is only the first step; robust governance further demands that the presence and contributions of those human reviewers be formally documented.
4. What must remain transparent?
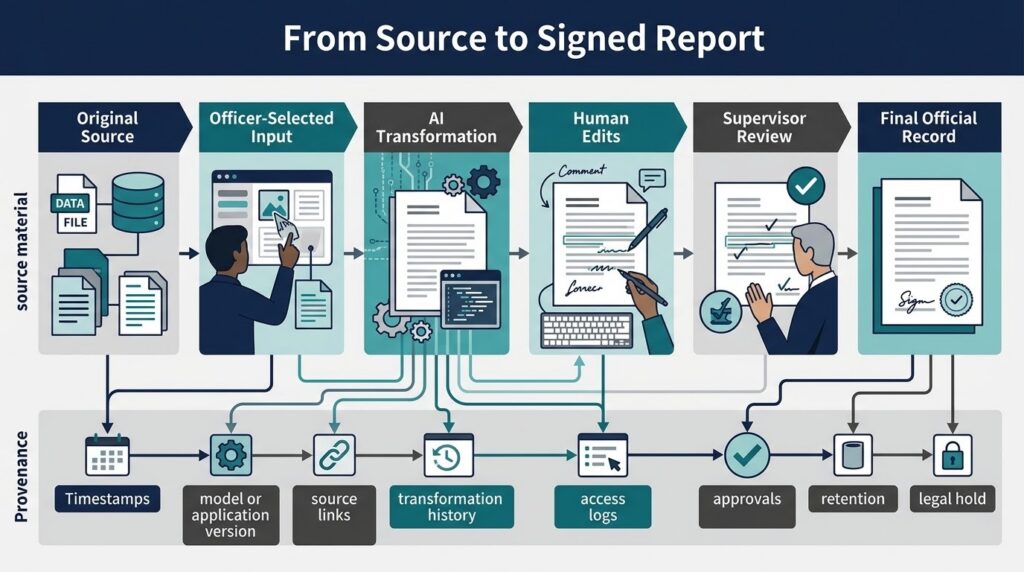
Chris: A supervisor shouldn’t have to re-listen to hours of body-camera audio to know whether an AI-assisted report is trustworthy. What they need is a version history: what the officer originally said or wrote, what the AI generated from it, and what changed between draft and final. Without that, review becomes a formality instead of an actual check.
This is also where a generic disclosure line falls short. “This report was written using AI” tells a defense attorney nothing about what the AI actually did: whether it transcribed, structured, or interpreted. California’s SB 524 gets at this by requiring identification of each AI program used, officer verification, retention of the first AI-created draft, and a minimum audit trail identifying the person who used AI and any video or audio used to create the report. That’s the right level of specificity; not just that AI was involved, but what it touched.
Lili: The version history Chris describes is the practical meaning of transparency. The World Economic Forum and OECD efforts on common metrics and comparable disclosure reflect the same institutional need: a consistent language for implementation across systems. Here, that language must support evidentiary review. “AI was used” does not show whether the system transcribed, structured, summarized, or interpreted the source. The record should identify the source, the transformation, the AI program, the human edits, and the final approval in a form that supports correction and challenge.
5. How is sensitive information protected?
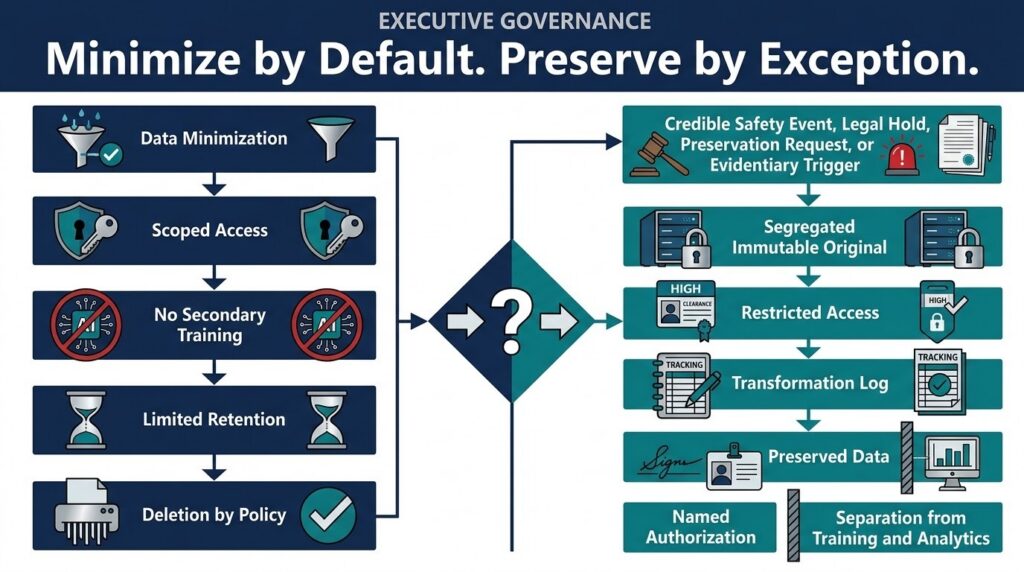
Chris: Start with the data-flow question: where does agency information actually go, who has access, including vendor support staff and any subprocessors, and is the deployment cloud, private cloud, or on-premises. Then ask a narrower question most agencies skip: does the design even need to capture more than the minimum? A system built on officer dictation only ever touches what the officer chose to say. A system built on continuous ambient audio or full video analysis is, by design, capturing bystander conversations, unrelated radio traffic, and visual details that have nothing to do with the incident. All of that now has to be protected, retained, and eventually deleted or produced under discovery.
Narrower input isn’t just a workflow choice; it’s a smaller attack surface and a smaller retention liability. CJIS and related requirements still have to be evaluated for the specific agency and deployment, but the starting footprint matters before you get to contract language.
Additionally, proper data privacy agreements need to be in place, and “the agency owns the data” needs to mean something contractually, not just appear as a line item. Flock Safety is the cautionary example here. The company’s terms nominally grant agencies ownership of their own data, but an ACLU review of Flock’s changed terms and conditions found the company also secured the exclusive right to determine and control the method, timing, format, and medium of access to the data that supposedly belongs to the customer, after earlier language promising Flock would not sell customer data quietly disappeared. The Los Angeles Police Department hit this same gap directly: it began renegotiating its Flock contract in mid-2026 specifically to secure ownership of all data and metadata collected, and to bar Flock from distributing that data or using it to train AI. Ownership language in a contract means little if the vendor still controls how and when the agency can get its own data back, or whether that data feeds the vendor’s model training.
Consider the use of client-side encryption as well, and ask the vendor to be specific about what it actually protects. Two different questions are often collapsed into one: does the AI processing the data ever leave a closed loop the agency controls, and separately, can the vendor’s own staff view the data in unencrypted form? A closed-loop architecture means the input is processed entirely within the agency’s contracted environment rather than routed out to a third-party model provider. Client-side encryption addresses the second question. It doesn’t need to block the AI from reading the text to do its job, but it should mean that engineers, support staff, or anyone else at the vendor cannot pull up an agency’s raw, unencrypted data. Those are two separate protections, and an agency should get a clear answer on both, not just an assurance that the data is “encrypted” without knowing who it’s actually being kept from.
Lili: The data-flow and encryption questions Chris identifies are where privacy by design becomes practical. The whole point is that privacy is not a final-stage compliance check bolted onto a system after the vendor has already been selected. A recent privacy-by-design framework for child-facing large language model applications takes familiar principles such as data minimization, purpose limitation, transparency, accountability, security by design, user rights, and meaningful consent where applicable, and applies them across the full lifecycle: data collection, model training, operation and monitoring, and continuous validation. For an agency, that means collecting only what the use case requires, prohibiting secondary training by default, limiting access, keeping secure logs, making AI transformations visible, and treating model or configuration changes as governance events rather than invisible software updates.
6. What happens when AI gets it wrong or misses the big picture?
Chris: Name the failure modes plainly: wrong names, misread license plates, ambient audio treated as relevant when it wasn’t, or, in video-analysis tools, an inference presented as fact. Tools that extract findings from every video frame create a specific version of this problem: an officer can be handed a draft asserting something like “suspect had a weapon” based on the AI’s read of the footage, not the officer’s own observation. If that officer doesn’t catch it, they can end up testifying to something they never actually saw, because the draft reshaped their memory of the event before they ever took the stand.
The correction path has to be real, not theoretical: officer review before submission, supervisor sampling after, and training that explicitly targets automation bias. Officers need to be taught to challenge the draft, not defer to it because it sounds official. Systems that clearly separate “this is what you said” from “this is what the AI generated” make that challenge easier. Systems that hand back a single polished narrative make it harder.
Vendors should also provide complete audit trails of how the AI interacted with the input, including not just the final output but what changed along the way. Two things make that trail useful instead of decorative: the system should visibly flag any content in the draft that can’t be traced back to something the officer said or provided, and it should track its own error and hallucination rate over time rather than leaving agencies to discover the rate through casework. A vendor that can’t produce either of those isn’t offering an audit trail; it’s offering a transcript with no way to tell what the AI added.
Lili: The correction path Chris describes should connect to the agency’s incident process. Once an error survives review, it may have influenced an arrest, charging decision, discovery response, or testimony. The agency needs a named owner, severity criteria, escalation, and a method to correct downstream records. The first task is reconstruction: source input, generated output, system version, human edits, approvals, and downstream use. An audit trail should help fix the case and determine whether the same failure affected other reports, not simply prove that someone clicked “approve.”
This risk is not merely theoretical; documented cases, such as those detailed in the ACLU’s reporting on facial recognition, highlight instances of mistaken identity that have led to wrongful accusations, underscoring the critical need for strict governance around AI-based identification tools.
7. What evidence justifies expanding deployment?
Chris: Measure the thing you actually set out to fix in Question 1: not general satisfaction, but total report-completion time. In the first Manchester study, Adams et al. measured the period from opening a report template through submission for review and found no statistically significant reduction in report-writing time. The authors note that narrative generation is only one part of a larger workflow that still requires structured data entry and documentation concerning witnesses, victims, suspects, evidence, property, and other incident details. A 2025 follow-up survey by Boehme et al. adds the implementation picture:
- Eighty-eight percent of treated officers used the tool, for about 36% of their reports.
- Fifty-two percent reported issues such as omitted details, body-camera timeline mismatches, and extensive editing.
- Among users, 29% perceived time savings, 67% no difference, and 4% an increase. Supervisors perceived improvements in quality (64%), completeness (48%), accuracy (52%), submission speed (60%), and detail (60%).
A best practice would be to break results out by report type, unit, and complexity. A tool that works well for routine incident reports may perform very differently on complex or contested cases. Another helpful practice is to be clear about who produces what evidence: a vendor can hand over uptime and error logs, but correction rates, supervisor revision patterns, and prosecutor feedback need to come from the agency’s own independent tracking, not the vendor’s dashboard.
Lili: The two studies Chris notes are especially important here because the report does not stop with the officer. The follow-up study shows why agencies should distinguish objective completion time from officer and supervisor perceptions of quality and efficiency. Once a report enters the case file or evidentiary record, it moves through the justice system. In their first paper, Adams et al. examine downstream use by prosecutors, courts, lawyers, oversight bodies, and others. Drawing on Ferguson’s 2024 working paper, they identify potential effects on charging, discovery, plea bargaining, trial, and sentencing. More polished or detailed reports may also influence perceived credibility and increase legal-review burdens. This is why, as Chris notes, it is important for law enforcement agencies to document the human in the loop and the audit trail during the review process, because failure to do so may present substantial issues of authenticity and transparency during court proceedings and subsequent appellate review.
The follow-up analysis highlights a central paradox inherent to AI-generated work product: while it can enhance document polish and boost initial efficiency, it often introduces a net editorial burden. As legal professionals know well, the post-generation requirement to re-insert omitted details and correct AI inaccuracies can ultimately produce a mixed overall impact on productivity.
CONCLUSION
While the quality and sophistication of AI-generated reports will inevitably improve, the necessity of human oversight remains absolute. Monitoring, auditing, and refining these systems is not merely a best practice—it is the bedrock of trustworthy policing.
Ultimately, the goal of adopting AI in law enforcement should not be to simply generate faster text, but to create more reliable, transparent, and defensible records. By prioritizing governance, provenance, and active human accountability, agencies can ensure that technology strengthens the integrity of the case file rather than compromising it. As these tools continue to evolve, success will be defined not by the speed of the draft, but by the defensibility of the final record.
Contributor Biographies
Chris Ryan
Chris Ryan is Chief Product Officer at PoliceReports.ai and is a former law-enforcement command staff member with nearly fifteen years of experience across training, tactical operations, undercover operations, leadership, and management. His role spans product development, strategy, sales, and innovation.
Lili Kazemi
Lili Kazemi is General Counsel and AI Policy Leader at Anant Corporation, where she advises on AI governance, risk, compliance, contracts, and policy. She brings more than 20 years of experience across Big Law, Big Four, and federal government roles, with a background in international tax, regulatory strategy, and cross-border legal frameworks. She is completing her certification the London School of Economics and Political Science’s Ethics of AI Masterclass and writes The Human Edge of AI, a LinkedIn newsletter examining AI at the intersection of law, policy, work, and everyday life.
You can now also follow Lili on substack at https://substack.com/@lilikazemi
Subscribe – The Human Edge of AI
About Anant
At Anant, we help forward-thinking teams unlock the power of AI safely, strategically, and at scale. From legal to finance, our experts guide organizations in building workflows that act, automate, and aggregate without losing the human edge. We turn emerging technology into practical, scalable business capability.
Disclaimer
This article is for general informational and educational purposes only and does not constitute legal advice. Law-enforcement agencies should evaluate applicable federal, state, local, tribal, and territorial law; constitutional and evidentiary requirements; prosecutor guidance; public-records and retention rules; labor obligations; CJIS Systems Agency requirements; agency policy; and the specific architecture and contract terms of any proposed deployment.
This is the second installment in a multipart series on AI, criminal liability, evidence, and law-enforcement governance. The series began with “When AI Becomes Evidence, Who Is Culpable?” and will continue with “5 Chain-of-Custody Breakpoints When AI Touches Police Evidence” and “7 Contract and Governance Terms Every Law-Enforcement AI Program Needs.”
Cited Studies
Adams et al. (2024), No man’s hand: artificial intelligence does not improve police report writing speed. Randomized controlled trial of measured report-completion time.
Boehme et al. (2025), Writing at the speed of hype: officers’ post-experimental perceptions of AI report writing. Follow-up survey of officer and supervisor perceptions.
Addae et al. (2026), A Privacy by Design Framework for Large Language Model-Based Applications for Children. Research preprint proposing lifecycle privacy-by-design controls.